AI Agents Now Handle 46% of Research Tasks Alone. The Other 54% Is Human Judgment
OpenAI reports that its agents now complete nearly half of two- to four-hour research tasks without help, double the rate in March. The data confirms that AI makes teams stronger, but it also shows that human judgment, oversight and rules still shape the outcome.
 BySebastián RondónCEO y fundador de KMS Agency Group
A few days ago, OpenAI shared a number worth reading slowly: its AI agents now complete, with no human help, 46% of the research tasks that would take a person two to four hours. Back in March, that figure was 23%. In just a few months, it doubled.
It's tempting to stop at the headline and conclude that AI now does the work on its own. At KMS Agency, we read it differently. The number confirms that AI makes teams stronger, but it also shows very clearly where human judgment is still essential. And for any company planning to deploy agents, that second part is what decides whether the project succeeds or fails.
What the report actually says
The figures come from *Research acceleration: The jagged frontier*, the second report OpenAI has published on how AI is speeding up its own research. According to The Next Web's coverage, these are the key takeaways:
- Two- to four-hour tasks: agents complete them on their own 46% of the time, up from 23% in March.
- Four- to eight-hour tasks: the success rate rose from 13% to 35%.
- Usage per researcher: at API list prices, OpenAI's median researcher used around $2,400 a day in agent time in October, 62% more than in September.
- Work in parallel: by mid-October, more than two-thirds of researchers had at least four agents running at the same time during their peak usage.
These are big numbers. But the report itself contains the nuances we care about most.
A jagged frontier: excellent at some tasks, weak at others
OpenAI describes this progress as a *jagged* frontier, meaning uneven. Results vary widely depending on the type of task:
- Monitoring model training runs: 79% success without help.
- Answering technical questions: 72%.
- Writing code for inference and serving systems: 25%.
- Building evaluation and training environments: 29%.
The practical takeaway is simple: AI performs very well on tasks that are well-scoped, repetitive and easy to verify, and far less well on tasks that call for design, context and decisions with real consequences. This isn't an average that rises evenly across the board; it's a map of peaks and valleys.
OpenAI adds an honest caveat about its own data: as the agents improved, researchers were able to change which tasks they handed them. In other words, the success rate also reflects the human choice of what to delegate.
The ideas still come from people
For us, this is the most important point in the report. OpenAI asked key researchers where the main ideas behind its most recent models came from. On the post-training and safety teams, they credited every idea to people, with the models helping to build them out.
In interviews, researchers said agents still have "poor taste" in research ideas, code, data and writing, and that they need close supervision. One of them even admitted to being unsure how long that human edge will last. That is exactly why it makes sense to build oversight processes now, rather than waiting for the problem to show up.
There's another telling detail: Safety and Alignment was the area that grew the most in researcher time, with a 77% increase in documented work-weeks between January and September. The more capable agents become, the more human effort goes into keeping them in check.
The other 54%: judgment, oversight and guardrails
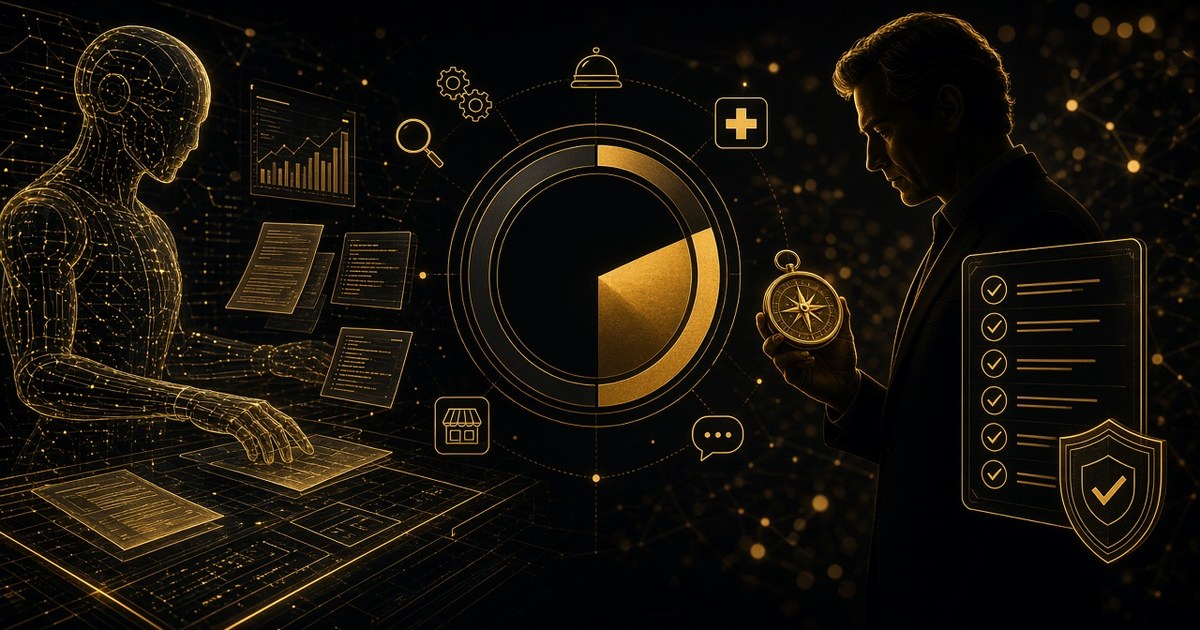
If agents handle 46% of those tasks on their own, the remaining 54% doesn't disappear. That's where judgment, review, exceptions and decisions with a real impact on customers, money and reputation live.
At KMS Agency, we see the same thing in every deployment. A well-configured AI agent answers questions, sends quotes, logs data and follows up at high speed. What makes the difference is everything around it:
1. Which tasks get delegated. Just as at OpenAI, the choice of what to hand the agent shapes much of the outcome. 2. Which rules it follows. Pricing, policies, tone, limits: what it can and cannot do. 3. When it asks for approval. Some decisions must go through a person before they're carried out. 4. Who reviews the results. An unsupervised agent is a risk, not a saving.
That's why we say AI doesn't replace teams: it makes them stronger. But only when someone with experience sets the framework.
What this means for a small business, a hotel or a clinic
The report is about a research lab, but the pattern applies to any company. The useful question isn't "Can AI do my job?" but "Which parts of my operation are well-scoped, repetitive and verifiable, and which parts need judgment?"
Service and retail SMBs
Answering frequent questions, logging leads in the CRM, sending follow-ups and booking appointments are all tasks an agent can take on very effectively. Negotiating a special price, handling an upset customer or deciding on an exception is still the sales team's job, with the agent preparing the information.
Hotels and vacation rentals
An agent can respond on WhatsApp around the clock, share availability, send rates and confirm booking details. But cancellation policies, blocks for events or a guest's special request call for clear rules and, often, sign-off from someone at the hotel.
Clinics and medical practices
The agent can guide patients on services, hours and requirements, and book or reschedule appointments. Anything involving clinical judgment, sensitive information or unusual cases must be escalated to the clinic's staff, without exception.
In all three cases, the agent brings speed and availability; the human team stays in control of what matters.
How to get started without losing control
Based on what the report shows and on our own experience deploying agents, we recommend this sequence:
- Map your tasks across customer service, sales and operations, and separate the well-scoped, verifiable ones from those that require judgment.
- Start with high-volume, low-risk tasks, where the agent is most likely to succeed.
- Write the rules and limits before you switch the agent on, not after the first mistake.
- Define human approval checkpoints for pricing, exceptions and sensitive decisions.
- Measure and adjust every week: what it resolved on its own, what it escalated and where it got things wrong.
Conclusion
The jump from 23% to 46% in just a few months shows how fast agent capabilities are advancing. But the same report makes it clear that success depends on which tasks agents are given, on supervision and on human judgment. The companies that will get the most out of AI aren't the ones that use it the most, but the ones that govern it best.
At KMS Agent AI, we design virtual employees that handle customer conversations and get work done across WhatsApp, CRM and email, with rules, limits and human approval from day one. If you'd like to know which parts of your operation an agent can take on and which should stay with your team, let's talk.